LeetCUDA
xlite-dev · xlite-dev/LeetCUDA
An agent skill that allows coding assistants to write and optimize high-performance CUDA kernels based on specialized learning notes and examples.
An Open-source book with Modern CUDA learning Notes for Beginners - BF16/FP8/FP4, HGEMM, CuTe, Flash-Attention, etc.
See it in action
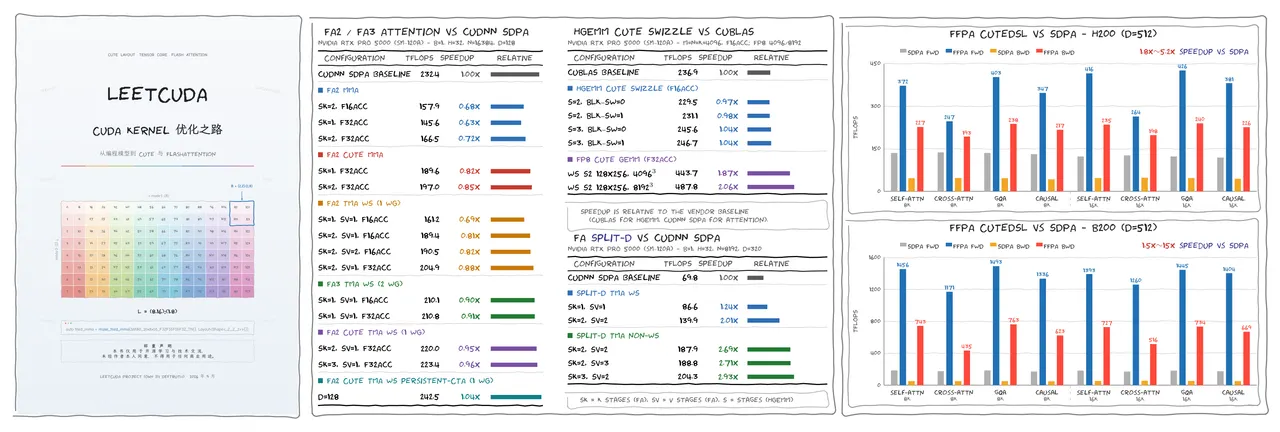
From the author's READMEPerformance benchmarks for CUDA kernels, GEMM, and Flash Attention
From the author's README xlite-dev ·Source
What you can do with it
- Have an agent write a custom high-performance HGEMM kernel using Flash-Attention knowledge
- Optimize existing C++/CUDA code by referencing the LeetCUDA book examples via the skill
- Debug memory efficiency issues in BF16/FP8 kernels using the agent's provided GPU expertise
Safety check
No risky patterns found in the files we scanned.
Automated scan of the repo files. Always review code you run.
From the README
📚 LeetCUDA: An open-source book of modern CUDA learning notes
It covers Tensor/CUDA Cores, 200+ CUDA kernels, HGEMM achieving 98%~100% of cuBLAS TFLOPS, FP8 & FP4 GEMM, and Flash-Attention built on Tensor Cores with pure MMA PTX. The LeetCUDA's open-source book is now available at ©️LeetCUDA.pdf (600+ pages) and online docs at leetcuda.io (zh, en). 🔥🔥🔥
Please also check out our production-ready Kernel Library: ffpa-attn - Fast and Memory-Efficient Exact Attention (BF16/FP16/FP8/FP4) for Large Headdim, 1.5x~15x🔥🔥 speedup over standard PyTorch SDPA.
📖 Quick Start
git clone https://github.com/xlite-dev/LeetCUDA.git && cd LeetCUDA
git submodule update --init --recursive --force && cd kernels/interview
# Install the latest cuBLAS & cuDNN for bench (remove the old version)
apt remove -y libcublas-cuda-13 libcudnn9-cuda-13 libcudnn9-dev-cuda-13
apt install -y cublas-cuda-13 cudnn9-cuda-13 && apt install -y ccache
# Blackwell (e.g., RTX 5090, PRO 5000/6000, recommended: CUDA>=13.2)
./build.sh --arch sm_120a && ./bin/leetcuda_bench_sm120a.bin --bench
🤖 Agentic workflow
LeetCUDA provides a leetcuda-cpp-kernel SKILL that reuse the knowledge and examples from the open-source book and repository. Users can use it with Coding Agents, e.g, GitHub Copilot, Claude Code, Open Code.
# Install the skill for different coding agents (recommended: gh>=2.101.0)
gh skill install xlite-dev/LeetCUDA leetcuda-cpp-kernel --agent opencode
gh skill install xlite-dev/LeetCUDA leetcuda-cpp-kernel --agent claude-code
gh skill install xlite-dev/LeetCUDA leetcuda-cpp-kernel --agent github-copilot
©️Citations
@misc{LeetCUDA@2025,
  title={LeetCUDA: An Open-Source Book of Modern CUDA Learning Notes for Beginners},
  url={https://github.com/xlite-dev/LeetCUDA.git},
  note={Open-source software available at https://github.com/xlite-dev/LeetCUDA.git},
  author={DefTruth and Many Others},
  year={2025}
}
📖 Click here to show the legacy contents
📖 Contents
- 📖 HGEMM-MMA 🎉🎉
- 📖 FlashAttention-MMA 🎉🎉
- 📖 200+ CUDA Kernels 🔥🔥
- 📖 100+ LLM/CUDA Blogs 🔥
- 📖 How to Contribute 👀👇
📖 HGEMM Benchmark 🎉🎉
Currently, on NVIDIA L20, RTX 4090 and RTX 3080 Laptop, compared with cuBLAS's default Tensor Cores algorithm, the HGEMM (WMMA/MMA/CuTe) in this repo (blue🔵) can achieve 98%~100% of its (orange🟠) performance. Please check toy-hgemm library⚡️⚡️ or HGEMM⚡️⚡️ repo for more details.
| 📚Feature | 📚Feature | 📚Feature | 📚Feature |
|---|---|---|---|
| ✔️CUDA/Tensor Cores | ✔️Loop over K | ✔️Tile Block(BMxBK) | ✔️Tile Threads(T 8x8) |
| ✔️WMMA(m16n16k16) | ✔️MMA(m16n8k16) | ✔️Pack LDST(128 bits) | ✔️SMEM Padding |
| ✔️Copy Async | ✔️Tile MMAs | ✔️Tile Warps | ✔️Multi Stages(2~4) |
| ✔️Register Double Buffers | ✔️Block Swizzle | ✔️Warp Swizzle | ✔️SMEM Swizzle(CuTe/MMA) |
| ✔️Collective Store(Shfl) | ✔️Layout NN | ✔️Layout TN | ✔️SGEMM FP32/TF32 |
📖 FA2-MMA Benchmark 🎉🎉
I have also implemented FlashAttention-2 using pure MMA PTX instructions, which supports features such as Multi-Stages, Tile MMA, Tile Warp, Shared KV SMEM, Fully Shared QKV SMEM, Prefetch Q s2r, Prefetch K/V g2s, QKV Fine-grained Tiling, Collective Store, etc. Please refer to flash-attn⚡️⚡️ for more details.
| 📚Feature | 📚Feature | 📚Feature | 📚Feature |
|---|---|---|---|
| ✔️Tensor Cores | ✔️Loop over N/D | ✔️Tile Block(Br, Bc) | ✔️MMA(m16n8k16) |
| ✔️Pack LDST(128 bits) | ✔️SMEM Swizzle/Padding | ✔️Copy Async | ✔️Tile MMAs |
| ✔️Tile Warps | ✔️Multi Stages(1/2) | ✔️Collective Store(Shfl) | ✔️Split KV/Q |
| ✔️Shared QKV SMEM | ✔️Prefetch Q s2r | ✔️Prefetch KV g2s | ✔️QKV Fine-grained Tiling |
Currently, for small-scale attention (B<=4, H <=48, SeqLen <= 8192, D <= 64) it can run faster than FA2/SDPA on some Devices. For example, on NVIDIA RTX 3080 Laptop, 📚 Split Q + Fully Shared QKV SMEM method can achieve 55 TFLOPS (D=64) that almost ~1.5x 🎉 faster than FA2. On NVIDIA L20, 🤖ffpa-attn method can achieve 104 TFLOPS (D=512) that almost ~1.8x 🎉 faster than SDPA (EFFICIENT ATTENTION). However, for large-scale attention, there remains a performance gap. Stay tuned for updates ~ (MMA Acc F16/F32, softmax Acc F32 vs FA2 MMA/softmax Acc F32, 👇Benchmark)
| Algorithm | (B,H,N,D) | RTX 3080 Laptop | L20 | RTX 4090 |
|---|---|---|---|---|
| FlashAttention-2 | (1,8,8192,64) | 37 TFLOPS | 100 TFLOPS | 145 TFLOPS |
| share-qkv+stage2 | (1,8,8192,64) | 55 TFLOPS | 99 TFLOPS | 221 TFLOPS |
| FlashAttention-2 | (1,48,8192,64) | 37 TFLOPS | 109 TFLOPS | 163 TFLOPS |
| share-qkv+stage2 | (1,48,8192,64) | 48 TFLOPS | 107 TFLOPS | **2 |